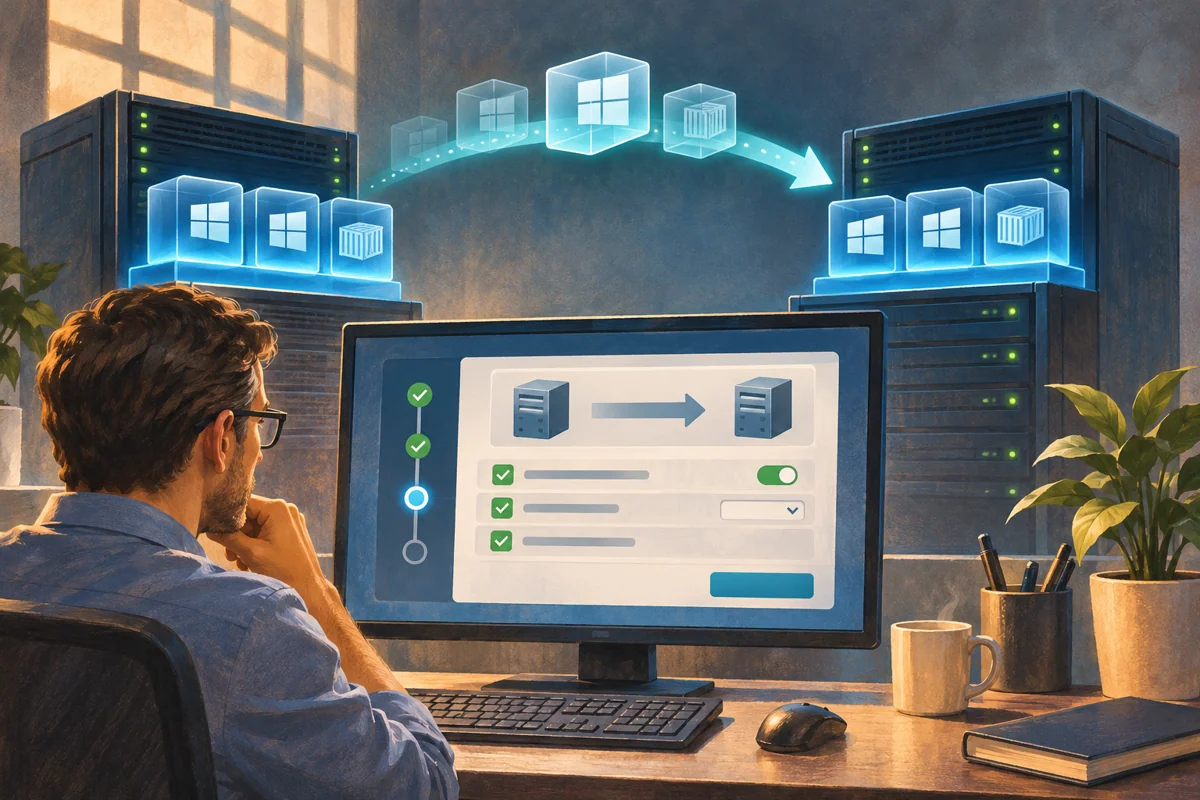
Platform: Windows Server 2019, 2022 and 2025, with the version and hosting restrictions described below.
Write the recovery runbook before enabling replication
A replica is valuable only when the organisation knows how to turn it into a working service. Hyper-V Replica sends VM disk changes asynchronously to a second host, which can support recovery after the primary location fails. It does not automatically reconcile applications, update every network dependency or guarantee that the latest transaction reached the recovery copy. Agree the permitted data loss and recovery time first.
Netcloud24 can prepare the replication arrangement and recovery environment within the managed service scope. Customers need clear recovery expectations and an escalation path; they should not be expected to start duplicate production VMs themselves. This article explains the infrastructure team’s setup and acceptance work for two standalone hosts using HTTPS certificate authentication. Clustered deployments require a Replica Broker and a corresponding cluster design.
Check whether the second host can run the service
Compare host versions, VM configuration compatibility, guest requirements and disk attachments. A recovery host with enough disk capacity may still lack the CPU, RAM or supported VM configuration needed to run the protected workload. Estimate simultaneous recovery demand rather than checking one small pilot VM in isolation.
Plan destination networks, DNS changes, application dependencies, certificate trust and access controls. An isolated test network is essential for rehearsing recovery without duplicating the primary server’s identity on production. Storage planning must include initial copies, ongoing change logs and retained recovery points. Independent backups remain necessary because unwanted changes can replicate too.
Measure the primary write rate and available intersite bandwidth. Initial transfer and steady-state replication impose different demands. If daily change exceeds the practical link capacity, a successful connection test will not prevent accumulating lag. Define monitoring thresholds in terms of the business recovery objective as well as Hyper-V’s health state.
Prepare certificate authentication and a restricted listener
Use suitable certificates on both hosts with accessible private keys and the authentication purposes required by Hyper-V Replica. Validate the expected host names, chain, validity and revocation path. The receiving host and primary host use their own local certificates; do not copy a thumbprint from one store and assume the corresponding key exists elsewhere.
On recovery host DR-HV02, create the approved storage location and configure certificate-only reception. The example permits only MAIN-HV01 through an explicit authorisation entry. Replace all certificate placeholders with values checked against the organisation’s PKI.
# On DR-HV02:
$receiverCertificate = 'REPLACE_WITH_DR_HOST_CERTIFICATE_THUMBPRINT'
New-Item -ItemType Directory -Path 'E:\RecoveryGuests' -Force | Out-Null
Set-VMReplicationServer -ReplicationEnabled $true `
  -AllowedAuthenticationType Certificate -CertificateThumbprint $receiverCertificate `
  -CertificateAuthenticationPort 443 -ReplicationAllowedFromAnyServer $false
New-VMReplicationAuthorizationEntry -AllowedPrimaryServer 'main-hv01.corp.example' `
  -ReplicaStorageLocation 'E:\RecoveryGuests' -TrustGroup 'MainOffice'
Inspect existing settings before running this on an established receiver. Changing authentication or the listener can affect other protected VMs. Enable the built-in HTTPS Replica firewall rule and apply the approved source scope, accounting for localised rule display names and upstream controls.
Prove the authenticated path before sending VM data
On MAIN-HV01, select its approved certificate and run the Replica connection test against the recovery FQDN. A TCP handshake on port 443 alone does not establish certificate trust or permission to replicate. Resolve authentication and authorisation problems before beginning the large initial copy.
$senderCertificate = 'REPLACE_WITH_MAIN_HOST_CERTIFICATE_THUMBPRINT'
Test-VMReplicationConnection -ReplicaServerName 'dr-hv02.corp.example' `
  -ReplicaServerPort 443 -AuthenticationType Certificate `
  -CertificateThumbprint $senderCertificate
Get-VMHardDiskDrive -VMName 'Orders-Test'
Check every attached disk and any excluded data against the application recovery requirement. A replica that deliberately omits a transaction volume needs an explicit application strategy; it is not a complete copy merely because the OS disk arrives. Preserve the chosen VM’s identity and configuration in the deployment record.
Protect a pilot and observe synchronisation
This example uses a five-minute change interval and three additional hourly recovery points. Those numbers are illustrative, not a guaranteed recovery objective. Application-consistent points require their own supported guest and policy configuration. More history also consumes more destination storage.
Enable-VMReplication -VMName 'Orders-Test' `
  -ReplicaServerName 'dr-hv02.corp.example' -ReplicaServerPort 443 `
  -AuthenticationType Certificate -CertificateThumbprint $senderCertificate `
  -ReplicationFrequencySec 300 -RecoveryHistory 3
Start-VMInitialReplication -VMName 'Orders-Test'
Get-VMReplication -VMName 'Orders-Test'
Measure-VMReplication -VMName 'Orders-Test'
Track initial synchronisation through completion, then inspect recent replication times, health and errors. Keep the normal replica off. Starting it directly beside the primary can create duplicate IPs, machine accounts or application writers. That is a split-brain risk, not a valid test of availability.
Run a rehearsal that demonstrates application recovery
Use Test Failover on the receiving host with a selected recovery point and the isolated network. Hyper-V creates a temporary test instance so the normal replication relationship can remain in service. Confirm that the recovered operating system boots, the expected data is present and the application can function with its required dependencies in the test arrangement.
Record the actual recovery point and what was checked. A test conducted without its database or identity service may demonstrate bootability but not full business recovery. Stop the test through the supported workflow and remove its temporary instance. Do not promote a test copy to production without the separate recovery decision.
Rehearse network mapping, DNS and access steps as well as VM startup. These tasks often dominate recovery time. For planned failover, the available primary can coordinate remaining changes. Emergency failover may select an older available point and lose recent work. In either case, prevent the old primary from independently serving the same workload before recovery production is brought online.
Investigate lag and maintain the trust lifecycle
For a certificate error, check expiry, private key, name matching, trust, revocation retrieval and the exact allowed-primary entry. For lag, compare write rate with bandwidth and examine destination capacity, latency and host pressure. Correlate timestamps across both hosts instead of repeatedly resynchronising without understanding the error. A resynchronisation can create considerable I/O.
Include certificate renewal and expiry monitoring in operations. A functioning relationship can fail months later when an unowned certificate expires. Validate the new authentication path during renewal and preserve a workable rollback until acceptance. Do not turn off revocation checking to hide a publication fault.
Retire or reverse the relationship deliberately
A recovery event needs an agreed failback or reverse-replication plan. Two diverged writable copies cannot simply be switched on together and expected to merge. Determine the authoritative workload, protect it and coordinate the application’s supported return process.
If a pilot is cancelled, preserve its backup and remove only its relationship after identifying the live production copy. Keep replica files until their recovery purpose is settled. Disabling the receiving listener is broader than removing one VM. The handover should include protected VMs, recovery-point policy, certificates, storage, isolated-test evidence and the people authorised to make a recovery decision.
 Preparing a Windows Server host for Hyper-V
Prepare an authorised Hyper-V host by reviewing hardware or nested support, collecting machine evidence, installing the role, verifying…
 Planning an external Hyper-V switch without losing host access
Design a Hyper-V external switch around reliable host access, explicit uplink and VLAN choices, then prove a test guest’s path and preserve…
 Provisioning a UEFI-based Hyper-V guest with PowerShell
Provision a supported Generation 2 guest from an agreed specification, configure UEFI and installation media, verify the first boot, and…
 Managing Hyper-V production checkpoints through a maintenance change
Use Hyper-V production checkpoints as a controlled maintenance tool, make fallback behaviour explicit, validate guest coordination, and…
 How to Configure Hyper-V Dynamic Memory
Applies to: Windows Server 2019, Windows Server 2022, and Windows Server 2025.Dynamic Memory adjusts virtual-machine RAM within safe…
